How AI Searches for Information: RAG, Grounding and SEO Impact
- Level: Advanced
- #AI Search
- #GEO
- #Advanced
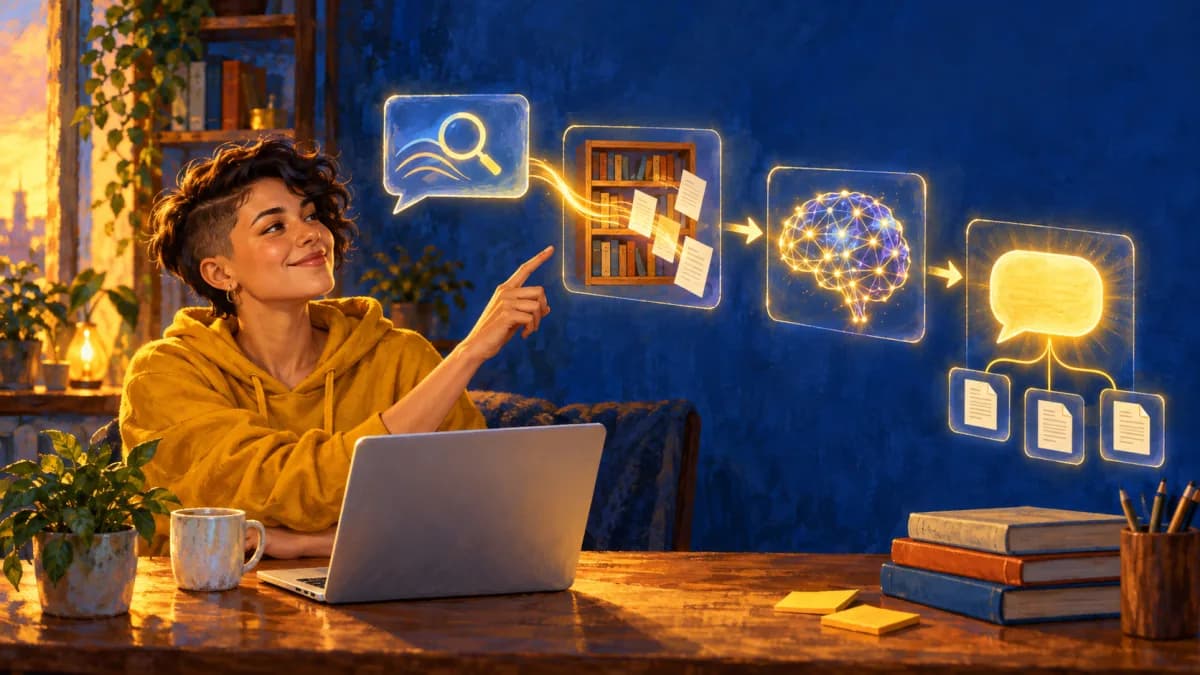
An AI assistant answers in one of two ways: from memory, using what it learned in training, or by checking sources on the spot. RAG (retrieval-augmented generation) and grounding are the technical names for the second way: the system searches for pages, selects passages and the model writes the answer supported by them. For SEO, this means that being crawlable, indexable and clear in key passages matters, as we explain in SEO, AEO and GEO.
Quick summary
- Training is fixed memory with a cutoff date. Retrieval is a live lookup in a document base or on the web. The citations you see come from retrieval.
- Google describes RAG as the technique (also called grounding) in which the model uses pages retrieved from the search index to generate the answer and show links.
- One question can become several searches (query fan-out). Your page can be retrieved by a sub-question you never aimed at.
- How each company selects and ranks passages is not public. What you can do is take care of what is verifiable: access, indexing, clarity and freshness.
- For Google, there is no markup or special file for getting into AI answers, and a citation is never guaranteed.
How to read this: if you are new to the topic, read "What is the difference between training and search?" and "How does a question become an answer?", and skip the technical callouts. If you already work in SEO, go to fan-out, the section on passages and the implications table.
What is the difference between what AI learned in training and what it searches for?
In training, the model absorbs patterns from an enormous body of text and stores them in its parameters, with no access to new pages. In retrieval, the system queries an external source at the moment of the question and hands the results to the model, which uses them to answer. The second way is what makes it possible to cite sources and talk about recent things.
The idea comes from an academic paper. Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks, by Patrick Lewis and colleagues (published in 2020 and accepted at the NeurIPS conference), combined the parametric memory of a language model with an external memory, in this case a dense index of Wikipedia, and showed improvement on tasks that require knowledge. Today, the documentation of products such as Gemini describes the same principle: the grounding with Google Search feature connects the model to real-time web content, to give answers beyond the knowledge cutoff and with citations.
In plain English: training is the exam you take from memory, using only what you studied. Retrieval is the open-book exam: you open the book, find the right chapter and answer while looking at it. Grounding is the rule that the answer must point to the page of the book where you found the information.
The consequence for marketing is direct. You have practically no control over getting into a model's training. Getting into retrieval depends on what you control today: the page being accessible, being found for the right sub-question and having a passage that answers it.
What are RAG and grounding?
RAG is the technique of fetching relevant documents and giving them to the model before it answers. Grounding is the goal: anchoring the answer in verifiable sources. Google treats the two as equivalent. In its guide to optimizing for generative AI features, it defines RAG (also known as grounding) as the technique that improves the quality, accuracy and freshness of answers, relying on Search's ranking systems to retrieve pages from the index and show links that support the information.
In practice, this explains why a page needs to be indexed and snippet-eligible: generative features are rooted in the ranking and quality systems that already existed.
For SEO professionals: "RAG" is an architecture, not a product. Each company decides the index (its own or a third party's), the number of documents retrieved, the passage size, the reranking and how the citation is attached. Only the publicly documented parts are citable. For the rest, what exists is inference from testing.
How does a question become an answer?
The path has five steps. The official documentation confirms the decision, search and citation steps; the selection and reranking of passages are not detailed by the companies.
- The system decides whether it needs to search. According to Anthropic's web search documentation, Claude searches when the request involves something current, changeable or outside its training, and answers directly when the knowledge is stable. In Gemini, the model analyzes the request and determines whether a search would improve the answer.
- It generates one or several queries. The model rephrases the question into searches that the system runs. The same Anthropic documentation says the process can repeat several times within one request, and that simple factual questions usually use 1 to 3 searches, while comparative research can use 10 or more.
- It retrieves candidates from an index. It may be Google's index (in Gemini and in Search's AI features) or another. Not every company says which index it uses.
- It selects the useful passages. This is where general RAG techniques come in, such as embeddings and reranking. There is no public documentation, company by company, of weights or criteria.
- It writes the answer with citations. In Anthropic's case, each citation carries a URL, a title and up to 150 characters of the cited text. In Gemini, citations come as annotations that link parts of the text to sources.
Notice that citation works by passage: the answer points to a specific passage, not to "the site." A good page with the answer buried tends to lose to an average one with the answer well placed in a clear block.
What is query fan-out and why does it change keyword research?
Query fan-out is the set of related searches the model generates at the same time to gather more information. Google gives an example in its guide: for "how to fix a lawn full of weeds," the fan-out might include "best weed killers for lawns," "remove weeds without chemicals" and "how to prevent weeds in the lawn." That is why a single question can retrieve very different pages.
For keyword research, the lesson is to cover the subtopics a person would need to resolve, not just the main keyword. We detail the mechanics in query fan-out.
There is a limit that Google itself sets: creating one page for every variation of a question, especially to manipulate answers, violates the scaled content spam policy. Cover the subtopics inside useful pages instead of generating hundreds of near-identical ones.
Hypothetical example: someone asks "what is the best practice management software for a small dental clinic that handles insurance billing?" The system could generate sub-queries such as "practice management software for small dental clinics," "insurance claims billing in dental software," "dental practice software pricing" and "insurance integration." A company with a specific page on insurance billing, with the answer in a short block at the top and the update date, can be the source for the second sub-query even without ranking for the full question. This is an illustration, not a real record of queries.
How does AI choose which passages to use?
Nobody outside knows precisely. What is documented is that Google has a passage ranking system, described in the ranking systems guide as an AI system used to identify individual sections ("passages") of a page and better understand their relevance to the search. For assistants in general, the common technical description is to cut documents into chunks, convert them into vectors (embeddings), compare them with the query and sometimes rerank the best ones.
In plain English: imagine your page is a book and the AI is short on time. It does not read the whole book, it looks for the paragraph that answers. If every section opens with the answer, it finds it fast. If the answer is spread over five paragraphs, it is easy to move on to the book next to yours.
There is a tension here. Google states, in the same guide, that you do not need to break content into tiny pieces for AI, because its systems understand several topics on a page and show the relevant part. In other words, no artificial "chunking." But sections with a clear heading and a direct answer help the reader and cost nothing. We detail this in LLM-citable content structure.
What changes for SEO in practice?
The emphasis changes, not the foundation. The table separates what is documented from what is good practice.
| Aspect | What is known | What to do |
|---|---|---|
| Eligibility on Google | The page must be indexed and snippet-eligible; the site must also be included in the generative AI control in Search Console | Check indexing and the control in the Search Console settings |
| AI crawlers | OpenAI documents OAI-SearchBot (appearing in ChatGPT search), GPTBot (training) and ChatGPT-User (user actions) | Define in robots.txt who can access what; see robots.txt and AI crawlers |
| Freshness | Anthropic's search API returns a page_age field for each result | Keep a visible update date and review data that changes |
| Citation by passage | Citations point to passages (up to 150 characters quoted in Anthropic's case) | Open each section with the direct answer |
| Subtopic coverage | Fan-out retrieves pages for sub-questions | Answer the central sub-questions without creating near-duplicate pages |
| Other indexes | Each assistant uses its own index or a third party's and does not always say which | Cover Bing and IndexNow too; see Bing Webmaster and IndexNow for AI |
OpenAI's documentation on its crawlers has three details: sites that block OAI-SearchBot do not appear in ChatGPT search answers; blocking GPTBot signals that the content should not be used for training; and a robots.txt change can take about 24 hours to take effect. These are separate decisions: you can appear in search and refuse training.
For SEO professionals: according to OpenAI, ChatGPT-User is not used to crawl the web automatically, and robots.txt rules may not apply to it because it is triggered by the user. Whoever audits logs should separate these three agents in their analyses instead of treating "AI bot traffic" as a single block.
How do you audit a page with RAG in mind?
Audit in pipeline order. Each step is a stage where the page can be eliminated before the answer is written.
- Access. Do robots.txt and server rules allow the crawlers that matter to you? Review accidental blocks.
- Indexing. Is the page indexed and free of
noindex? Confirm in Search Console with URL inspection. - Coverage. List 5 to 10 sub-questions a person would have about the topic and check whether the page, or the cluster, answers them.
- Passage. Rewrite section openings with the answer first, in 40 to 70 words.
- Freshness. Update data, prices and dates, and show the date of the last review.
- Test. Ask the questions in two or three assistants, note which sources appear and what your page is missing compared with the cited ones. Repeat every month. Contentor's AI Visibility tracks, on the questions you choose, whether ChatGPT cites your brand (ChatGPT only).
For a broader optimization workflow, see SEO for AI Search.
Frequently asked questions
What is RAG, in one sentence?
RAG is the technique in which the system fetches relevant documents and hands them to the model before it answers, so the answer uses current information and can cite sources. The name comes from a 2020 paper. Google uses the term as a synonym for grounding in Search's AI answers.
Do I need to worry about model training or only about search?
For immediate visibility, search is what you control: access, indexing and clarity of passages. On training, you can decide whether or not to allow your content to be used, for example with GPTBot in robots.txt in OpenAI's case. It is a separate strategic decision, and blocking training does not stop you from appearing in search-based answers.
Does splitting text into short blocks help AI?
It helps the reader and may help extraction, but Google says you do not need to fragment content just for AI. The best criterion is usefulness: sections with a clear heading and a direct answer work for people and for retrieval systems.
Does RAG guarantee the AI answer is correct?
No. RAG improves the chance that the answer rests on sources, but the model can still misread a passage or cite a source that does not support the claim. That is why, when testing your brand, you should open the cited links and check that the passage really says what the answer claims.
Next step
If you have not yet checked crawler access, start with robots.txt and AI crawlers, then write extractable passages with LLM-citable content structure. For the next step on the advanced path, move on to the step-by-step GEO audit. If your bottleneck is producing the pages that answer the sub-questions, generate articles with AI on Contentor with question-style headings and direct answers.
Read also:
Prepare your content for AI answers
Create AEO/GEO briefs, entities, schema, and structured articles for Google AI Overviews, AI Mode, and traditional SEO.
Try Contentor freeStrengthen your authority for AI Search
Combine source-worthy content with contextual backlinks on vetted sites to reinforce trust, discovery, and topical authority.
View contextual backlinks